Informazioni sul modello
Flux-Kontext-LoRA Text-to-Image converts clear prompts into fast, high‑quality images while supporting efficient LoRA fine‑tuning for styles, brands, and products. Its unified setup pairs a vision‑language model for reasoning with a diffusion renderer for fidelity, enabling instruction‑guided edits, spatial grounding, and identity‑preserving generations. Start with concise prompts and, for precision, add visual cues like bounding boxes. LoRA ranks up to 128 often balance speed and quality; higher ranks may add compute with limited gains. Iterate on prompts and cues for multi‑subject layouts or product placement. Ideal for marketing visuals, e‑commerce assets, personalized art, and rapid prototyping with consistent results.
Funzionalità
Esempio di risultato
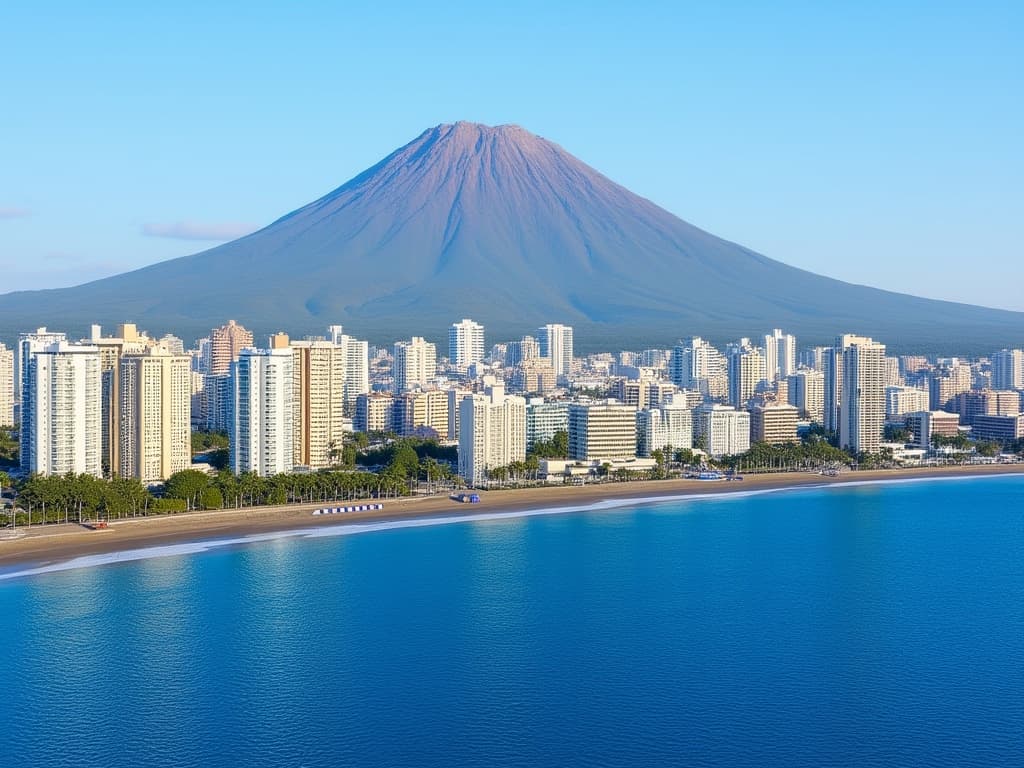
A realistic daytime scene of a coastal city with a majestic volcano in the background. The foreground shows seaside buildings and shoreline details, with the blue ocean meeting the city. Clear sky, natural daylight, sharp textures, and a bright realistic atmosphere.